Training and evaluating models that answer questions about images.
My work
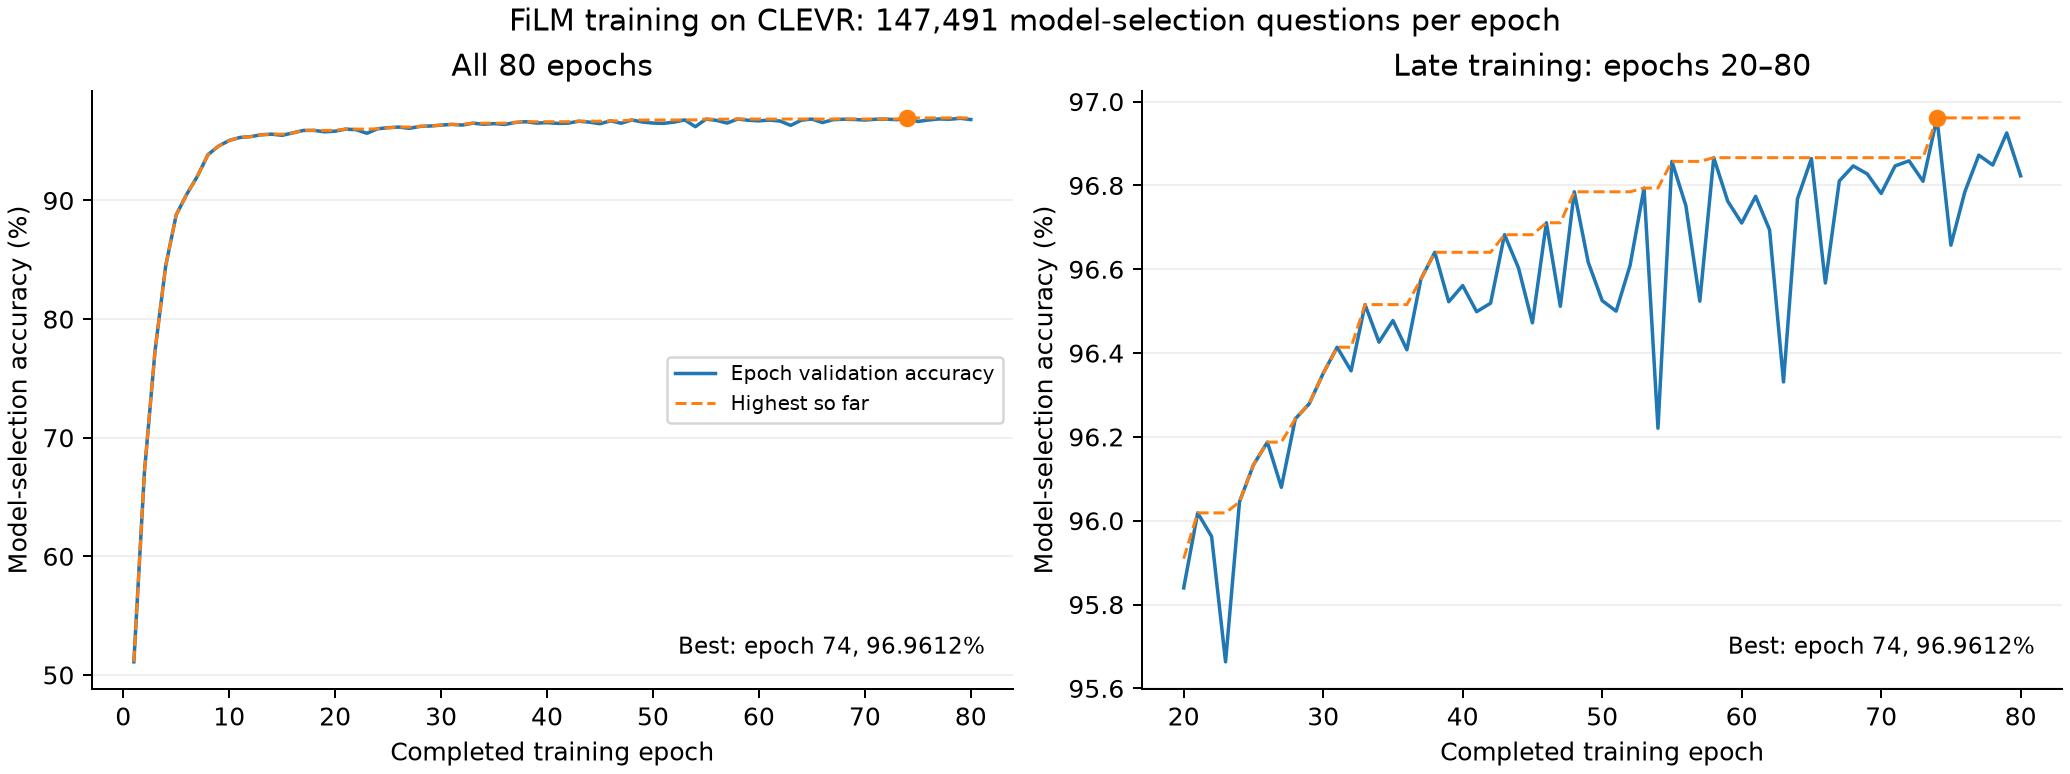
As part of the AIEA Lab's episodic memory research, I worked through visual question-answering tasks on CLEVR and CLEVRER. I set up the training and evaluation pipeline on Nautilus and trained FiLM for 80 epochs on 70,000 images.
The results
On the full validation set of 149,991 questions, the provided FiLM checkpoint scored 96.8431%. My selected trained checkpoint scored 96.9552%. The pretrained NS-VQA model scored 99.8133%.
The full validation set includes questions used for checkpoint selection. These results are a comparison within this task, not evidence that I created a new state-of-the-art model.